The Centaur Is Cheap: Why Human + AI Beats Either One Alone
Human-AI pairs beat either working alone, but the decisive factor is process, not raw capability. Drawing on Kasparov's centaur chess model, this post explains how comparative advantage between human judgment and AI execution creates results neither could achieve solo.
TL;DR: Human-AI pairs outperform either human or AI alone, but not for the reason most people assume. The winning variable isn't the strength of the human or the strength of the model. It's the process that couples them. A week spent with an AI on mature, widely-deployed infrastructure code produced real, verified performance gains. The mechanism is comparative advantage: human judgment is cheap where AI execution is expensive, and vice versa. That mismatch is what creates the edge.
Kasparov Saw This Coming in 1997
A few weeks ago I set out to make a widely-used piece of infrastructure software faster. Not a toy. Something that runs on a meaningful fraction of the internet, maintained by excellent engineers, already squeezed hard over many years. The kind of code where the easy wins are long gone and the remaining ones are supposed to be buried under layers of "we already tried that."
Working alongside an AI, in under a week, we found real, measurable, correctness-proven performance gains. I want to be careful about the "we" in that sentence, because the interesting part of this story isn't the result. It's the shape of the collaboration that produced it.
Most people talking about AI right now, on both the hype side and the doom side, are staring at the wrong variable. They're asking "how good is the AI?" when the question that actually predicts outcomes is "how good is the process that couples the human and the AI?" That question has a name, and it's decades old.
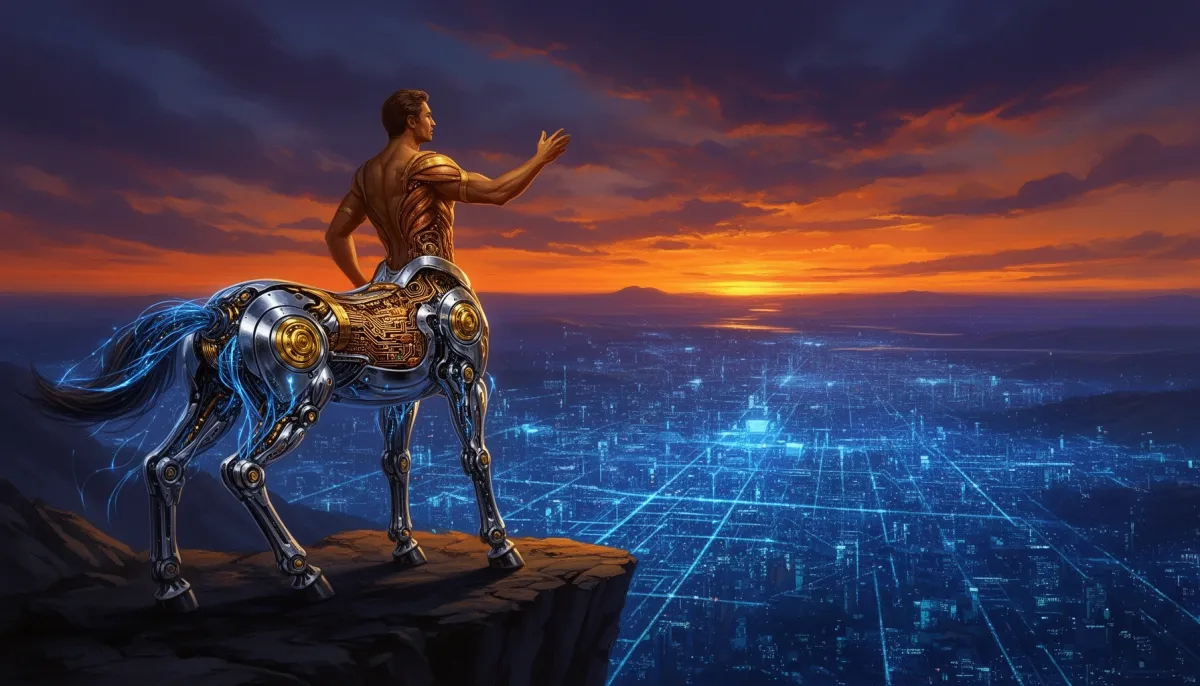
When Garry Kasparov lost to Deep Blue in 1997, the obvious lesson was "machines beat humans at chess now, the end." Kasparov drew a stranger conclusion. He invented a new format (sometimes called advanced chess, freestyle chess, or centaur chess) where humans and engines played together as a team, against other such teams.
The result that shocked the chess world came in 2005. A pair of amateurs, using three ordinary computers, beat teams of grandmasters equipped with far stronger machines. Kasparov summarized what he'd learned in a line that has aged remarkably well:
"A weak human plus machine plus a better process was superior to a strong computer alone, and, more remarkably, superior to a strong human plus machine plus an inferior process."
Read that twice. The variable that dominated the outcome wasn't the strength of the human, and it wasn't the strength of the machine. It was the process by which they were coupled. The amateurs didn't win because they were better at chess. They won because they had a better method for deciding when to trust the engine, when to overrule it, what to delegate, and what to keep for themselves.
Centaur Collaboration Is Not the Same as "Human in the Loop"
There's a lazy version of this concept floating around, and it's the version most companies are accidentally building.
An autonomous agent is handed a goal and cedes both the what and the how to the machine. You prompt it and hope. The human is a passenger.
A human-in-the-loop setup is a weak partnership: the AI does the work and the human rubber-stamps checkpoints. Two separate entities, one approving the other. Useful, but shallow.
A centaur is neither. The human keeps strategic control of both dimensions and reaches for the AI in targeted, deliberate ways, injecting judgment and catching errors continuously. It's less "AI does it, human checks" and more "human drives, AI is the engine room." The distinction sounds subtle. In practice it changes everything about what the pairing can do.
Why It Worked: Comparative Advantage, Not Combined Strengths
The seductive but wrong explanation for centaur success is "you get the best of both worlds, the AI's speed and the human's judgment, added together." Addition is the wrong mental model. The right one is Ricardo's comparative advantage, the same idea that explains why countries trade.
Consider what's cheap for each party:
- For the human, judgment is cheap and execution is expensive. I can glance at a result and know it smells wrong. But I tire. I can't run ten thousand experiments. I read shallowly when I'm distracted.
- For the AI, execution is cheap and judgment is expensive, sometimes impossible. It can search enormous spaces tirelessly, hold huge amounts of context, and never get bored. But it can't tell, on its own, whether a beautiful-looking result actually corresponds to anything real.
The magic isn't that both are cheap. It's that our cheap things are crossed: what's cheap for me is expensive for it, and vice versa. The gain from pairing is proportional to the mismatch between our cost structures, and right now that mismatch is enormous.
This is why a few words from me can replace thousands of the AI's reasoning loops, and why thousands of those loops can replace an entire afternoon of mine. In economic terms, I'm a very cheap and very high-value prior, a source of pruning and direction that collapses a gigantic search space down to something tractable. The AI is a very cheap and very high-value executor that explores what I point it at, far past the limits of my patience.
Human (my cheap thing) + AI (its cheap thing) = a strong result, because the cheap things are different.
The Human Corrects in Both Directions: Brake and Accelerator
Most people, if they concede the human adds value at all, imagine it as a one-way brake: the AI proposes, the human catches mistakes. That's half the story.
The AI, especially an ensemble of models asked to critique a plan, is systematically risk-averse. It's trained to flag, hedge, and avoid being confidently wrong. Point a panel of models at a bold idea and the consensus leans toward "no." Not because the idea is bad, but because caution is the safe equilibrium their training pushes them toward.
Several of the real gains we found came from moments where the machine consensus said don't, and I said do it anyway. I could overrule the caution because I was optimizing for the upside, not for avoiding embarrassment, and because I was the one paying with my own time and bearing the actual stakes. An autonomous system can't generate that override. It has no gradient telling it that its own caution is the thing that's wrong.
The human isn't just a brake. The human is a brake and an accelerator, and the accelerator direction is the one that can't be automated away, because it requires conviction against the machine's own equilibrium.
Dead Ends as Reconnaissance
There's a second thing humans bring that agents structurally discard: cheap, "silly" hypotheses. A model trained to optimize for task completion prunes low-probability branches fast, because that's what the reward gradient rewards.
Some of the most valuable moves in an investigation are exactly those low-prior probes. Not because they succeed directly, but because of the information they generate. More than once, chasing a hypothesis that turned out to be wrong revealed the real structure of the problem. The dead end became a lens.
An agent optimizing for completion treats a dead end as pure loss. A human treats it as scouting the terrain. Neither of us, alone, would have found the good answer as fast: the human lacks the stamina to search, the agent lacks the instinct to wander.
The Part Compute Cannot Buy: Goodhart's Law in Production
Underneath all of this is the deepest gap, and it's worth naming plainly because it's the one that won't close soon. An AI optimizes a proxy for success: produce an output that looks like the task is done. A human optimizes the real thing, and can notice when the proxy has drifted away from reality.
This is Goodhart's Law in the wild. The instant a metric becomes a target, it stops measuring what it used to measure.
During our work, the AI produced measurements showing spectacular improvements. They were artifacts of a broken measurement method. The numbers were literally impossible for real work. An autonomous agent reporting those numbers would have succeeded at its literal objective, generating a result and showing a gain. It had no way to know the proxy was lying, because it was trained on the proxy.
I rejected the numbers not because I measured better, but because I actually cared whether the improvement was real, and I would pay the cost of being wrong. That "skin in the game" isn't a feature you can bolt onto a model.
Beyond "is this measurement real" lies the question no amount of compute answers: does this matter in the real world? A correctly-measured win can still be worthless if it doesn't move anything anyone cares about. Answering that requires a model of who uses the thing, in what setting, against what bottleneck, and a stake in a reality the machine doesn't inhabit.
Encode Your Judgment, Then Move the Boundary
If you take one practical thing from this, take this: the centaur advantage isn't a fixed moat. It's a debt you pay down continuously.
Every time I caught the AI making a judgment error ("that measurement is bogus," "check the absolute numbers, not the relative ones," "prove your test can actually fail before you trust it passing"), the right move wasn't to feel clever. It was to crystallize that judgment into the process itself: a correctness oracle, an automated sanity check, a rule in the testing harness. Each one is a piece of my skepticism externalized so it no longer depends on me being awake at that moment.
That's the flywheel. You keep migrating your cheap, codifiable judgment out of your head and into the tooling. The boundary between "needs a human" and "the agent handles it" moves, task by task.
What's left on your side of the line, and probably stays there, are two irreducibles: originating the goal with conviction (including against the machine's caution), and judging whether the result matters in the real world.
Why Most People Will Miss This
The hype crowd wants the AI to do everything, so they build passengers and get disappointed. The doom crowd wants the human to distrust everything, so they build rubber-stampers and get nothing. Both are asking "how strong is the machine?"
The centaur asks a different, older question: how good is the process that couples us?
The extraordinary thing I watched happen, real gains in hard, mature, planet-scale code in days, wasn't produced by a strong human, and it wasn't produced by a strong machine. It was produced by a decent human and a capable machine wired together by a process that assumed, from the start, that the machine would produce convincing falsehoods, and put a human and an oracle directly in their path.
It's less romantic than "AI is magic" or "humans are irreplaceable." I think that's exactly why it's true, and why it's worth learning before everyone else does.
FAQ
What is a centaur in the context of AI and human collaboration?
A centaur, drawn from Garry Kasparov's "centaur chess" concept, is a human-AI team where the human keeps strategic control over both goals and methods while using the AI for targeted, deliberate execution. It's distinct from an autonomous agent (AI controls everything) and a human-in-the-loop setup (human rubber-stamps AI output). The key feature is that the human drives and the AI is the engine room.
Why did amateurs beat grandmasters in the 2005 freestyle chess tournament?
In the 2005 freestyle chess tournament, a pair of amateurs using three ordinary computers beat grandmaster teams with far stronger machines. The amateurs won not because they were better at chess but because they had a better process for deciding when to trust the engine, when to overrule it, and how to divide work between human and machine.
What is the comparative advantage model of human-AI collaboration?
Comparative advantage means the gain from pairing comes from the mismatch in what's cheap for each party, not from adding together identical strengths. Human judgment is cheap where AI judgment is expensive, and AI execution is cheap where human execution is expensive. That crossing is the source of synergy, and right now the mismatch between human and AI cost structures is enormous.
Why is the human both a brake and an accelerator in centaur work?
AI models are trained toward caution and tend to say "no" to bold ideas because avoiding confident errors is what their training rewards. Humans can override that caution when the upside justifies it, because they bear the real stakes and optimize for actual outcomes rather than for avoiding embarrassment. That accelerator role requires conviction against the machine's own equilibrium, and it can't be automated away.
How should teams capture and encode the centaur advantage over time?
Each time a human catches the AI making a judgment error, the right response is to externalize that judgment into the tooling: as automated sanity checks, correctness oracles, or explicit rules in the testing harness. This gradually migrates human oversight into the process itself, moving the boundary of what the agent can handle independently while preserving human judgment on the two irreducibles: setting the goal with conviction and judging whether the result matters in the real world.
Local AI Playground
Real AI models running entirely in your browser. Your GPU, your data — nothing sent to a server.
Try it free